As AI coding agents become increasingly capable of generating and modifying software at incredible speeds, it’s becoming clear that teams can’t verify the output fast enough. The generation of software has scaled horizontally, but verification must keep pace to avoid uncertainty.
Faster AI generated code testing without verification leads to uncertainty, which can be disastrous in the long run. Code that can’t be verified is like a mystery box, full of unknown variables that can cause crashes, bugs, and security vulnerabilities. The faster the code is generated, the more uncertainty it brings.
The paradox of faster uncertainty is a pressing issue in AI native development, where the speed of code generation seems to be outpacing the speed of verification. As a result, teams are left with a significant gap between what they can generate and what they can verify. This gap can lead to delays, rework, and even project abandonment.
In the context of AI generated code testing, teams need to adapt to this new reality and find ways to verify the code as quickly as it’s being generated. This requires a new approach to testing, one that can keep pace with the speed of code generation. The stakes are high, and the consequences of not verifying code can be severe, making it essential to find a solution to this paradox.
The Green-Test Trap in AI Generated Code Testing
A large green test suite can still be broken by a single issue. This might seem counterintuitive – after all, a comprehensive test suite that covers all the code is supposed to guarantee its reliability. But the reality is that a single weakness in the system can still cause the entire thing to come crashing down.
Mocked dependencies can conceal real system failures. When writing automated tests for code that relies on external libraries, it’s tempting to use mock objects to simplify the testing process. But this can lead to a false sense of security – if the mocked dependencies don’t accurately reflect the behavior of the real system, then the tests won’t catch any issues that arise from the interactions between the code and the external library.
Researchers warn against agent-generated tests lacking semantic value. This is a critical concern in AI-generated code testing, where the focus is often on producing large volumes of tests quickly and efficiently. But if those tests don’t have any real meaning or value, then they’re not actually doing their job – they’re not helping to ensure the reliability and stability of the code.
The Limitations of Code Coverage in AI Generated Code Testing
Code coverage measures lines executed, not test strength or failure. This sounds straightforward, but it’s a crucial distinction when it comes to AI generated code testing.
While code coverage metrics may look impressive, they don’t necessarily reflect the quality of your tests. In other words, a high code coverage percentage doesn’t guarantee that your tests are thorough or effective. In fact, a recent warning suggests that agent-generated tests can pass without adding any real value.
This raises a critical question: are we relying too heavily on code coverage metrics? Should we be looking beyond the numbers to ensure that our tests are truly effective? Testing must go beyond simple metrics to provide meaningful insights into our code’s behavior. By focusing solely on code coverage, we risk overlooking weaknesses in our tests and our code.
Code coverage metrics only tell part of the story. They don’t account for complex edge cases, unexpected inputs, or the nuances of human behavior. In reality, code is rarely used in isolation, and real-world scenarios often involve multiple factors that can affect its behavior. By ignoring these complexities, we may be creating a false sense of security that can come back to haunt us when our code is deployed in production.
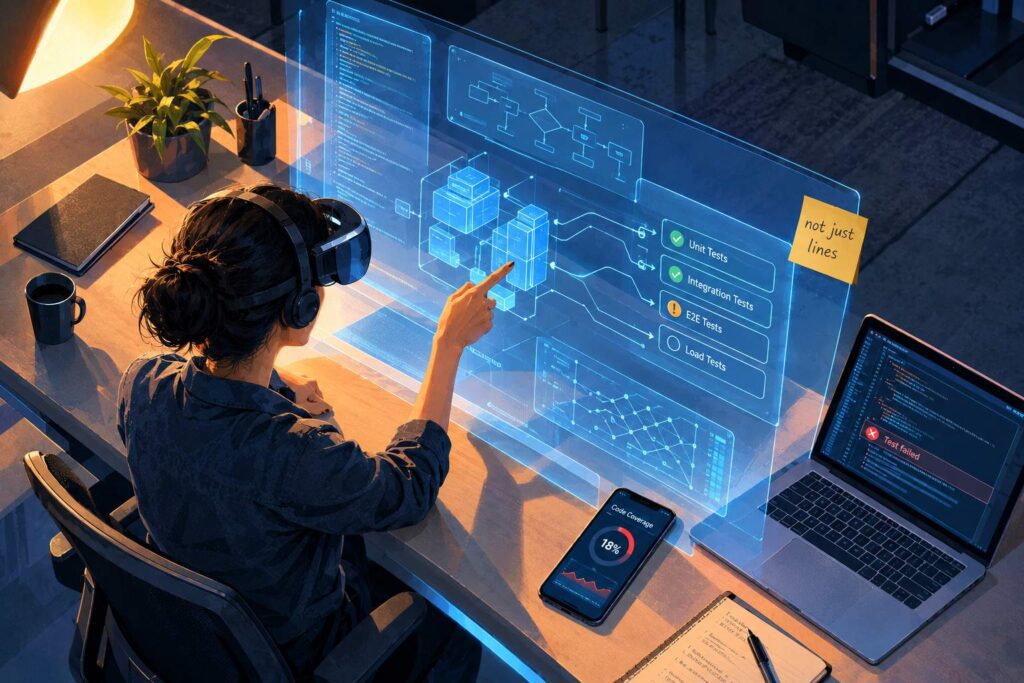
The Value of Integration Tests in AI Generated Code Testing
Integration tests reveal the real interactions between APIs and dependencies, showcasing how different components work together seamlessly. But when it comes to AI generated code testing, this becomes a challenge. The problem lies in the fact that AI-generated failures often occur at boundaries that are masked by mocks, making it difficult to identify the root cause of the issue.
The use of mocks can make it seem like a component is working as expected, when in reality, it’s only a simulation. This is where integration tests come in, providing a critical verification layer that ensures the code is working as intended in a real-world scenario. By testing the interactions between multiple components, integration tests can help identify issues that might be hidden behind a layer of mocks.
One of the key benefits of integration tests in AI generated code testing is that they can help developers identify issues early on. By testing the interactions between different components, developers can catch problems before they become major issues, saving time and resources in the long run. This is especially important in AI generated code testing, where the complexity of the code can be difficult to manage.
Smarter Testing for AI Generated Code Testing
The test pyramid should focus on behavior-oriented tests, taking into account the unique needs of AI-generated code. This approach ensures that tests cover the desired behavior of the code, rather than just its internal workings. By doing so, developers can gain confidence in the code’s functionality and reduce the likelihood of bugs slipping through.
Unit, integration, and other test types should be combined for a comprehensive testing strategy. This includes unit tests that verify individual functions or methods, integration tests that check how different components interact with each other, and other types of tests such as end-to-end tests or property-based tests. The goal is to create a robust testing framework that covers all aspects of the code’s behavior.
AI-generated code requires diverse testing strategies, as its complexity and unpredictability can make it difficult to anticipate and detect bugs. By incorporating a range of test types and focusing on behavior-oriented testing, developers can mitigate these risks and ensure that their AI-generated code is reliable and trustworthy.
The New Engineering Skill of Verification Design in AI Generated Code Testing
Software correctness is no longer a gamble when engineers build independent evidence of its quality. This crucial step ensures that code behaves as expected, reducing the likelihood of costly errors and downtime.
Verification design, once an afterthought, has become a critical skill for software development teams. It involves designing code with verification in mind from the very beginning. By doing so, teams can catch mistakes early on and avoid the costly delays associated with finding and fixing them later.
Testing, however, is not just a single event. It’s a multi-layered process that requires verification at every stage. This includes unit tests, integration tests, and end-to-end tests, each playing a vital role in ensuring that software behaves as intended.
Effective verification design is more than just a checklist of items to tick off. It requires a deep understanding of the code and its requirements. It demands that engineers think critically about the code they write, anticipating potential problems and designing solutions that can be verified.
The benefits of verification design are numerous. It saves time and resources by reducing the need for costly debugging and rework. It improves confidence in the code, allowing teams to deploy software with greater speed and accuracy.
Verification design is not a one-time event but an ongoing process that requires vigilance and attention to detail. It’s a mindset that engineers must adopt to ensure the quality of the software they create.