

When developers first build a Retrieval-Augmented Generation (RAG) system, they usually follow what’s now known as “classical RAG“: chunk documents, convert them into dense vector embeddings using an API like OpenAI, save them to a vector database, and query them with cosine similarity. It feels like magic in a proof of concept. In production, it hits a wall fast.
This article walks through why that wall exists, and how we solved it by building a hybrid search RAG pipeline that combines dense vectors, sparse keyword matching, and a free local reranking step – no extra paid APIs required.
Here’s what’s covered:
- Why dense embeddings alone fail on exact identifiers, codes, and names
- How to combine BM25 keyword search with dense vector retrieval
- Why hybrid search RAG pipeline barely adds any latency or cost
- How to add local cross-encoder reranking without paying for a hosted API
- Real bugs we hit building this pipeline, and how we fixed them
- Common architectural questions: exact matching, context size, and alpha weighting
The RAG Scaling Wall: Why Dense Embeddings Alone Fall Short
The fundamental issue with classical RAG is that dense embedding models compress an entire paragraph of text into a single, fixed-size mathematical array – typically 1,536 floating-point numbers. That compression is lossy. In this semantic vector space, words are mapped by conceptual proximity rather than exact characters. This is fantastic for understanding synonyms (mapping “issues with renewal” to “problems extending contract,” for example), but it fails at capturing exact keyword matches.
Consider a typical enterprise query containing a strict alphanumeric code, a specific date, or a customer name – searching for a note about account rep_001, or checking details on a contract for “Acme Corp.” In a dense-only search, the embedding model prioritizes the general semantic concept of the sentence, often drowning out the critical identifier. A document discussing “Acme Corp renewal” can score lower than an unrelated but heavily descriptive document about generic contract templates.
Trying to fix this by switching to larger embedding models, or fragmenting text into microscopic chunks, only increases API overhead, fragments context, and raises inference latency – without addressing the core limitation. Vector models simply don’t index text character by character.
Inside the Hybrid Search RAG Pipeline Architecture: Marrying BM25 and Dense Vector Retrieval
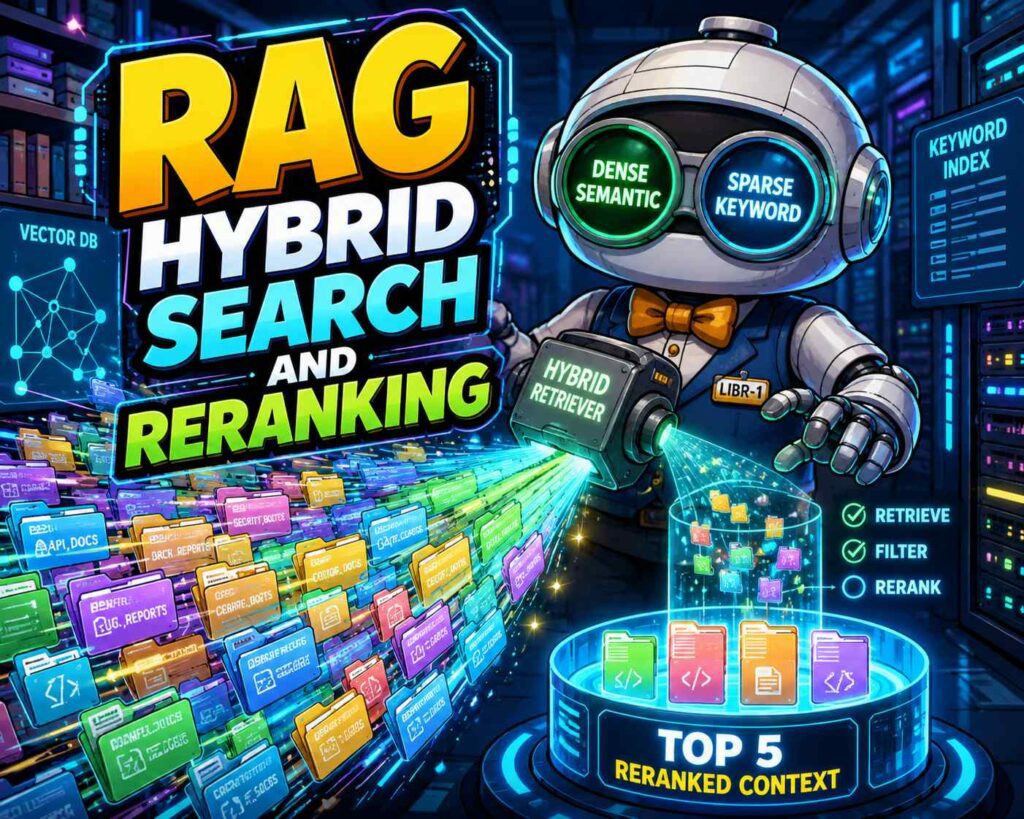
To overcome the limits of semantic-only search, modern retrieval engines use hybrid search RAG pipeline. It combines two different indexing philosophies in a single query: dense retrieval (captures meaning) and sparse retrieval (captures exact keywords).
For the sparse component, we integrated the BM25 algorithm using the free, open-source library pinecone-text. Unlike dense search, which relies on neural networks to compute embeddings, BM25 operates on term frequency and document frequency. It tokenizes the corpus, stems the words, filters out stop words, and assigns statistical weight to rare terms.
While building this, we updated the ingestion pipeline in ingest.py to generate both representations. A key architectural decision was managing the state of the BM25 encoder. Unlike dense embedding models, which use pre-trained, static parameters, BM25 needs to be trained (fitted) on the target document corpus so it knows which words are rare and which are common:
# Initialize and fit BM25Encoder on the corpus of text
# hybrid search RAG pipeline
from pinecone_text.sparse import BM25Encoder

bm25 = BM25Encoder()
logger.info("Fitting BM25Encoder on document text corpus...")
bm25.fit(texts)

# Save the fitted parameters to JSON
BM25_PARAMS_PATH.parent.mkdir(parents=True, exist_ok=True)
logger.info(f"Saving BM25 parameters to {BM25_PARAMS_PATH}...")
bm25.dump(str(BM25_PARAMS_PATH))
By serializing the BM25 state to a local file (data/bm25_params.json), we solved a real engineering constraint: the live FastAPI server can run index lookups and encode search queries on demand, without holding or loading the entire raw text corpus in memory. Ingested documents are upserted into Pinecone using a unified structure containing both dense values and sparse_values.
The Cost-Performance Sweet Spot: Why Hybrid Search RAG Pipeline Barely Costs Anything
A common point of confusion for backend developers is the latency and cost of running hybrid queries. If a query needs both dense embeddings and a sparse keyword lookup, doesn’t that double the retrieval overhead?
The short answer is no. Vector databases use specialized index structures like Hierarchical Navigable Small World (HNSW) graphs to navigate multi-dimensional dense spaces in milliseconds. Traditional keyword search uses inverted indexes – a simple lookup table mapping words to document IDs. When you run a hybrid query, the database executes both index lookups concurrently. For a database containing millions of documents, this entire math-based retrieval step takes less than 10 milliseconds, since it operates purely on pre-computed numerical indexes without analyzing or processing raw document text.
This inexpensive search forms the first stage of our hybrid search RAG pipeline. Instead of fetching the final target count (say, the top 5 documents) directly from the database, we query for a larger candidate pool – top 15 or top 50 – using hybrid search. This stage acts as a wide, high-recall net:
# Executing Pinecone hybrid query to fetch a larger candidate pool
results = index.query(
    vector=dense_vector,
    sparse_vector=sparse_vector,
    top_k=15,  # Retrieve more candidates for reranking
    namespace="documents",
    filter=filter_dict,
    include_metadata=True
)
This design ensures we don’t miss relevant documents due to vector compression limits, while keeping the database round trip fast and cheap.
Implementing Local Cross-Encoder Reranking Without Paid APIs
Once we have our candidate pool of, say, 15 documents, the second stage of the pipeline kicks in: reranking. Stage one compares queries and documents as independent vectors. Stage two uses a cross-encoder model, which processes the query and document text together in a single neural network pass. That lets the model compute attention weights between individual words in the query and the document, producing a far more accurate relevance score.
Running a cross-encoder against a database of a million documents would be computationally impossible in a live request. Running it against just 15 candidates returned by hybrid search takes only a few milliseconds.
To keep the project free and self-contained, we used a local reranking model from the sentence-transformers library:
class MockCrossEncoder:
    """A mock CrossEncoder for testing/offline scenarios to avoid downloading models."""
    def predict(self, pairs: list[tuple[str, str]]) -> list[float]:
        scores = []
        for query, doc in pairs:
            q_words = set(query.lower().split())
            d_words = set(doc.lower().split())
            overlap = len(q_words.intersection(d_words))
            scores.append(float(overlap) / (len(q_words) + 1))
        return scores

def get_cross_encoder():
    """Return a singleton CrossEncoder model, or a MockCrossEncoder if MOCK_EMBEDDINGS=true."""
    global _cross_encoder_instance
    if _cross_encoder_instance is None:
        if os.environ.get("MOCK_EMBEDDINGS", "false").lower() == "true":
            logger.info("Using MockCrossEncoder (MOCK_EMBEDDINGS=true).")
            _cross_encoder_instance = MockCrossEncoder()
        else:
            from sentence_transformers import CrossEncoder
            model_name = os.environ.get("RERANK_MODEL_NAME", "cross-encoder/ms-marco-MiniLM-L-6-v2")
            _cross_encoder_instance = CrossEncoder(model_name)
    return _cross_encoder_instance
By choosing cross-encoder/ms-marco-MiniLM-L-6-v2 as our default local model, we get a small, highly optimized network that runs fast on standard CPU hardware – no GPU required. For local testing, we added the MockCrossEncoder fallback, which mimics semantic relevancy scoring using token-overlap statistics. That lets integration tests run fully offline, without internet access or GPU resources.
Post-Mortems from the Field: Debugging BM25 State and Test Expectations
Engineering projects are rarely smooth, and expanding this codebase surfaced two bugs worth sharing, since both highlight common pitfalls in search architecture.
The BM25 Serialization Bug
Our first integration test run failed with a cryptic exception:
Failed to load BM25 parameters: BM25Encoder.load() missing 1 required positional argument: 'path'
Looking closely at the pinecone-text source code, we realized that despite returning an instance of the class, BM25Encoder.load is actually defined as an instance method:
def load(self, path: str) -> "BM25Encoder":In our initial implementation, we mistakenly called it as a class method:
encoder = BM25Encoder.load(str(BM25_PARAMS_PATH))Because of that signature, Python treated our file path string as the self parameter, leaving the actual path argument empty. We fixed it by instantiating the object first, then calling load:
encoder = BM25Encoder()
encoder.load(str(BM25_PARAMS_PATH))
The Candidate Leakage Test Failure
Another failure showed up during ranking validation. The test inserted two documents – one highly relevant document about “Acme Corp contract renewal,” and one unrelated document about the weather – then asserted:
assert "weather" not in contextThe test failed, but the bug wasn’t in our retrieval logic. It was in our test expectations. Since our test database only contained two documents total, and our RAG query retrieved the top 5 chunks (candidates[:5]), both documents were naturally returned in the final context, even though the weather document was correctly scored lower by the reranker (with a score of 0.0). We fixed the test by asserting relative ranking order instead of absolute exclusion:
# Query for Acme Corp and verify we retrieve the Acme document first
context = query_documents("Acme Corp renewal")
assert "Acme Corp" in context
assert context.startswith("Acme Corp")
Common Architectural FAQs
To wrap up, here are answers to the questions backend engineers ask most often when designing a system like this.
Does Hybrid Search Ever Use Exact String Matching?
Yes. Beyond BM25 sparse matching, which matches exact words, production database engines often combine vector queries with exact metadata filters (for example, {"doc_type": "meeting_note"}). Some setups also run traditional regex scans or prefix indexes in parallel to handle literal character matching.
How Many Documents Should You Keep After Reranking?
The top 3 to 10 documents – most commonly 5 – remains the standard, even with newer LLMs supporting 128k+ token context windows. Feeding dozens of documents into the model increases latency and cost. LLMs also suffer from the “lost in the middle” phenomenon, where they pay high attention to the beginning and end of a prompt but tend to ignore information placed in the middle. Keeping the context short and tightly sorted with a reranker is still the best practice.
How Do You Determine the Alpha Weighting?
The balance between dense and sparse search is controlled by an alpha parameter: score = alpha * dense_score + (1 - alpha) * sparse_score. An alpha of 0.5 is a balanced starting point. If your users search for specific serial numbers or code tags, lower alpha to around 0.3 to favor sparse (keyword) matches. If queries are more conversational or semantic, raise alpha to around 0.7.
Key Takeaways for Building a Hybrid Search RAG Pipeline
- Dense embeddings alone can’t handle exact identifiers. Codes, names, and dates need sparse keyword matching alongside semantic search.
- Hybrid search is nearly free. Vector and keyword indexes run concurrently in milliseconds, even at millions of documents.
- Reranking is what makes the final results accurate. Cast a wide net with hybrid search, then let a cross-encoder sort the small candidate pool.
- You don’t need a paid reranking API. A small local cross-encoder model runs fast on CPU and keeps the pipeline free and self-contained.
- Serialize stateful components like BM25 carefully. Instance methods and class methods aren’t interchangeable – a subtle mismatch here can silently break retrieval.
- Write tests against relative ranking, not absolute exclusion, especially with small test datasets where every document may still appear in the final context.
A hybrid search RAG pipeline with local reranking gives you the recall of dense embeddings, the precision of exact keyword matching, and accurate final ordering – all without adding meaningful latency, cost, or a dependency on a paid reranking API. The full implementation can be found in this GitHub repository.