

Traditional security principles may seem like a relic of the past, but they still hold relevance in the realm of AI agent security. However, their application requires adaptation to the unique challenges posed by these systems. The age-old mantra of “secure by design” takes on a new meaning when applied to AI, where the lines between code and behavior are increasingly blurred.
Probabilistic model behavior is now a fundamental aspect of an AI system’s attack surface. This is an area that was once considered the exclusive domain of machine learning engineers, but it’s now a pressing concern for security professionals. By embracing this reality, we can begin to develop more effective countermeasures to address the unique risks associated with AI agent security.
The security landscape of AI is evolving rapidly, with new threats and vulnerabilities emerging at an alarming rate. As AI becomes increasingly integrated into our daily lives, the need for robust security measures becomes more pressing. This means that security professionals must be prepared to adapt and evolve their strategies to keep pace with the changing landscape of AI agent security.

Understanding Prompt Injection Risks
When you interact with an AI agent, it’s not just the information it provides that you should be concerned about. External content can be untrusted input, and that’s a crucial distinction to make.
This external content can take many forms, including web pages and emails. Think about it – have you ever clicked on a link in an email or visited a website without thinking twice about where it was coming from? That’s exactly how prompt injection can happen.
Prompt injection is a type of attack where an agent is tricked into performing a task that it wasn’t designed to do. This can be achieved through indirect prompt injection, where an attacker manipulates the input to the agent in a way that hijacks its functionality.
The problem is, web pages and emails can be malicious. They may look harmless at first glance, but they can contain code that’s designed to manipulate the agent. This code can be crafted to trick the agent into performing a specific task, or to reveal sensitive information.
So, what can you do to protect yourself? Treat web pages and emails with caution. Be wary of links and attachments, and don’t click on anything that looks suspicious.
Applying Least Privilege Principle
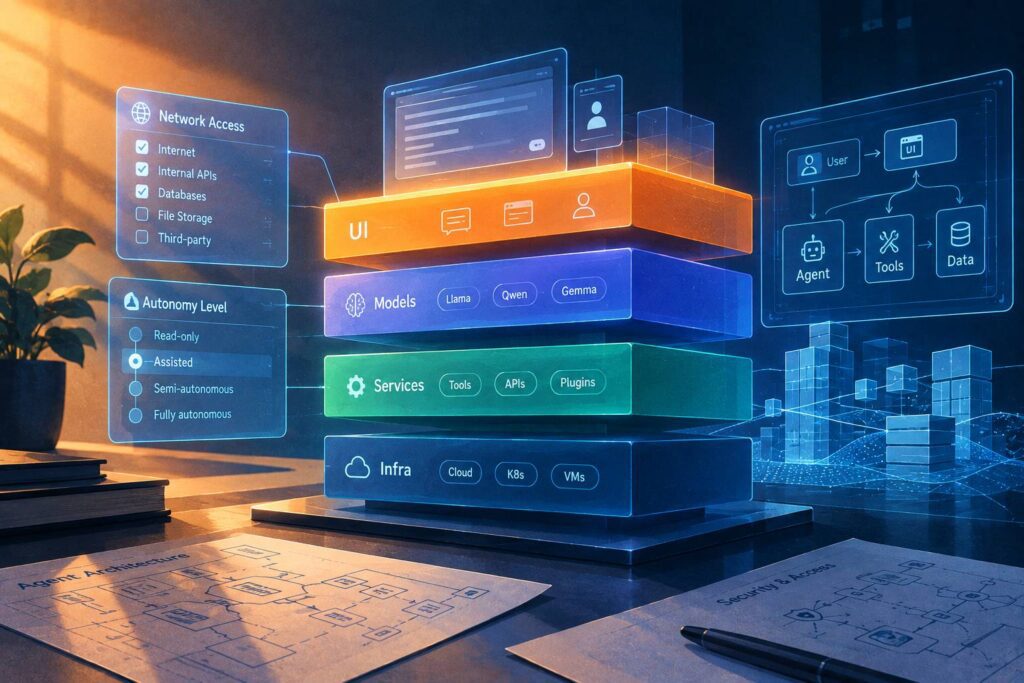
When designing AI agents, it’s essential to grant them only the minimum permissions and capabilities necessary to perform their tasks. This concept is known as least privilege principle, and it’s a crucial aspect of maintaining security.
Limiting autonomy to task requirements ensures that agents don’t have the freedom to make decisions that could compromise security. For instance, an agent tasked with data analysis should only be able to access the data it needs to perform its analysis, and nothing more.
Restricting credentials and network access is also vital, as it prevents unauthorized access to sensitive information. This can be achieved by using role-based access control, where agents are assigned specific roles that dictate their level of access.
By implementing these measures, you can significantly reduce the risk of security breaches and minimize the potential damage they could cause. It’s worth noting that even a small mistake can have far-reaching consequences, so it’s crucial to be meticulous when granting permissions and access.
Securing Tools and MCPs
When it comes to security, treating tool servers and plugins as part of the security boundary is crucial. This means considering them as an integral part of the overall system, just like any other component. Think of it as a digital fortress, where every entrance and exit is carefully guarded.
APIs and tool outputs should be carefully vetted to ensure they don’t introduce any vulnerabilities. This is especially true when it comes to sensitive information or high-risk operations. Think of it as a quality control check, where every output is scrutinized to ensure it meets the desired standards.
Untrusted extensions should be blocked or restricted, as they can pose a significant risk to the security of your system. This includes any third-party plugins or add-ons that may have been compromised or are of unknown origin. By limiting access to such extensions, you can significantly reduce the attack surface and prevent potential breaches.
For instance, in the context of AI agent security, untrusted extensions can cause significant harm if they’re able to manipulate or exploit the system. This is why it’s essential to exercise caution when dealing with external components, and to always prioritize the security of your system above all else.
Implementing Effective Sandboxing
Isolating agent execution with filesystem boundaries is crucial in preventing malicious activity. This means limiting the agent’s access to sensitive data and resources, reducing the attack surface and potential damage in case of a breach.
Network and credential isolation is also essential in protecting the agent from potential threats. By restricting the agent’s communication with external systems and limiting its access to credentials, you can prevent unauthorized access and exploitation.
Sandboxing prevents agent escape and exploitation by creating a secure environment for the agent to execute. This environment is isolated from the rest of the system, preventing the agent from accessing sensitive data or causing harm.

Protecting Data and Enforcing Approval
To prevent sensitive data from entering model context, it’s essential to ensure that it doesn’t reach the model at all. This can be achieved by implementing robust input validation and sanitization mechanisms. This involves carefully examining the data before it’s processed, ensuring that it conforms to expected formats and doesn’t contain any malicious content.
When a high-impact action is required, it should be handled with caution. This is why requiring human confirmation is a must. By doing so, we can prevent unintended consequences and ensure that only authorized actions are taken. This also helps in reducing the risk of errors and missteps.
Approval interfaces can be manipulated through injected content. This is a significant concern, as it can lead to security breaches and other issues. To mitigate this risk, it’s crucial to use secure and reliable approval interfaces that can’t be easily manipulated. This involves implementing robust security measures and closely monitoring the interfaces for any signs of tampering.

Conclusion: Embracing Evolving AI Agent Security
Traditional security skills need to be upskilled to keep pace with the rapid evolution of AI agent security. This means that security professionals must stay ahead of the curve by learning new skills and adapting to emerging threats.
Threat modeling and testing are essential components of AI agent security. By identifying potential vulnerabilities and testing for weaknesses, organizations can ensure that their AI systems are secure and reliable. Effective threat modeling and testing require a combination of technical expertise and creative thinking.
The security of AI agents will continue to evolve rapidly as new technologies emerge. As AI becomes more integrated into our daily lives, the need for robust security measures will only grow. This means that organizations must be proactive in staying ahead of potential threats and continually updating their security protocols.
Security professionals must be prepared to adapt to new technologies and emerging threats. This requires a combination of technical expertise, creative thinking, and a willingness to learn and evolve. By upskilling and staying ahead of the curve, security professionals can help organizations protect their AI systems and maintain trust in these increasingly critical technologies.
